Note
Click here to download the full example code
Prisoner's dilemma tournament
Agents play six-round prisoner's dilemmas against each other with strategies coded as genomes that answer the opponent's last two moves. The fittest reproduce with rare mutations, and the population never settles: cooperative eras, when reciprocating strategies dominate, alternate with eras of exploitation and mutual defection.
One hundred agents start from random genomes and evolve for 3000 steps. The default blueprint shows the mean score per round, which wanders between about 1.4, close to mutual defection at 1, and 2.7, close to mutual cooperation at 3.
import matplotlib.pyplot as plt
import numpy as np

from skcomplex.engine.runtime import Simulation
from skcomplex.engine.viz import RerunObserver
from skcomplex.models import create

MODEL = 'prisoners_dilemma_tournament'

system = create(MODEL, random_state=0)
observer = RerunObserver(MODEL, save_path=f'{MODEL}.rrd', blueprint='default', interval=12)
simulation = Simulation(system, observers=[observer], random_state=0).check().prepare().run(until=3000)
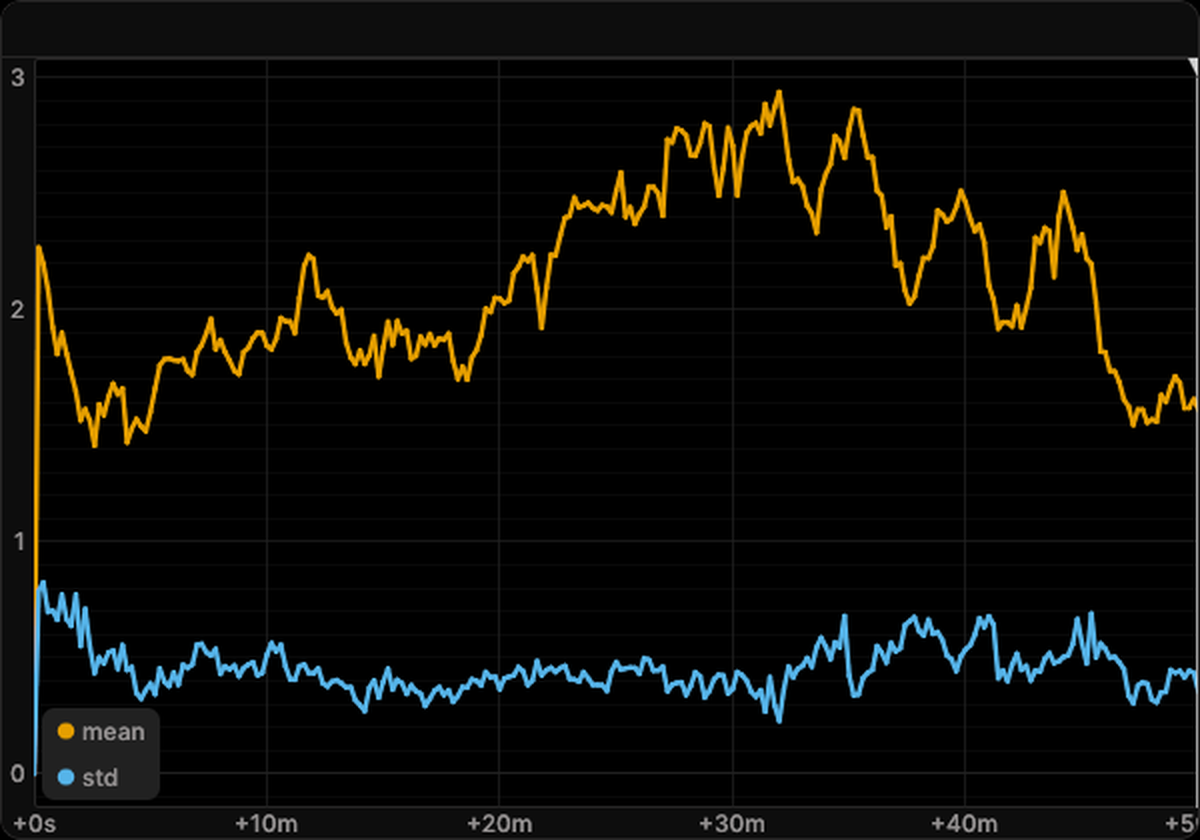
Open the recording in the Rerun viewer
Eras of strategies
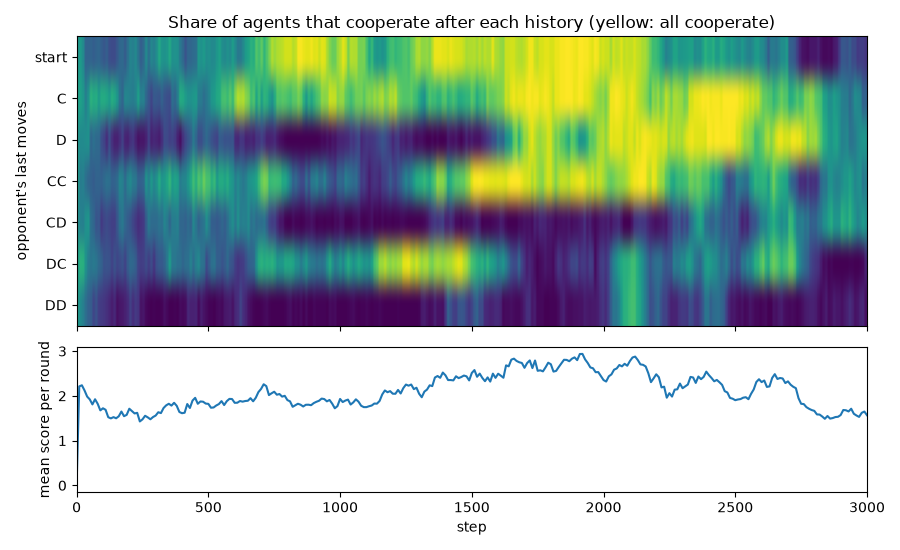
Each gene answers one history of the opponent's last moves. The share of agents that cooperate on each history
should switch between eras in step with the mean score: the score is high when the answer to the opponent's
cooperation (genes C and CC) is cooperation, and falls when exploiters that defect after C spread.
trajectory = simulation.trajectory_
frames = range(0, len(trajectory.times), 10)
genes = np.array([np.asarray(trajectory.agents('agents', frame).values['genome']).mean(axis=0) for frame in frames])
scores = [np.mean(trajectory.agents('agents', frame).values['fitness']) for frame in frames]
times = np.asarray(trajectory.times)[list(frames)]
fig, (strategy, score) = plt.subplots(2, 1, figsize=(9, 5.5), sharex=True, height_ratios=[2, 1])
strategy.imshow(genes.T, aspect='auto', cmap='viridis', extent=(times[0], times[-1], 6.5, -0.5), vmin=0, vmax=1)
strategy.set_yticks(range(7), ['start', 'C', 'D', 'CC', 'CD', 'DC', 'DD'])
strategy.set_ylabel("opponent's last moves")
strategy.set_title('Share of agents that cooperate after each history (yellow: all cooperate)')
score.plot(times, scores)
score.set_xlabel('step')
score.set_ylabel('mean score per round')
fig.tight_layout()
plt.show()
About the model
The evolution of strategies of the iterated prisoner's dilemma from random genomes.
References
- Axelrod 1984
- Downey 2018
Total running time of the script: ( 0 minutes 7.577 seconds)
Download Python source code: plot_prisoners_dilemma_tournament.py
Download Jupyter notebook: plot_prisoners_dilemma_tournament.ipynb